Oops! Something went wrong while submitting the form.
Most optimizers score your profile against a generic rubric. Sai reads the job description you're targeting, compares you to people already in that role, and drafts the rewrites.
The recording is a real session. The sheet on the right is what it produced.
Sai opens each profile, pulls the signal, and writes the row, live, in a real browser.
Eight columns, sorted by score, with a source link behind every claim.
A LinkedIn account you're already signed into, and a link to the job description you want to be a match for.
A written audit: a verdict on how your profile currently reads versus how the role needs it to read, the structural problems behind that gap, and drafted replacements for your headline, About section, and experience bullets.
About 8 minutes.
Re-run against a different job description whenever you target a new role, and Sai re-benchmarks from scratch.
LinkedIn profile optimization is the work of making a profile findable by the right recruiters and convincing once it is opened. These are two separate jobs. Findable means the profile contains the words recruiters type into LinkedIn's search box — recruiters search with the vocabulary of their own job postings, so a vocabulary mismatch removes a candidate from the result set before any judgement is made. Convincing means that when someone opens the profile, the headline and the first three lines of the About section give them a reason to keep reading. Most tools in this category address only findability, because findability is measurable against a fixed rubric, which is why most of them return a score. A score measures completeness. It does not measure fit against a specific role, and fit against a specific role is what determines whether a profile produces inbound.
Three situations. A working professional targeting a specific role whose profile still reads as their last job. A career changer whose experience supports the new target but whose profile is written in the vocabulary of the old field. An active job seeker running against several postings for the same kind of role. In all three the underlying task is identical and repeatable: read a job description, read the profile as it renders, read how people already in that role describe the same work, then rewrite three fields. That fixed shape is what makes it suitable for workflow automation rather than a one-off editing session.
A profile score grades against a fixed rubric — photo present, About section over 200 words, at least five skills listed, headline longer than the default. Each is a real signal, and none of them knows what job the user wants. A profile can move from 60 to 95 by filling in sections without changing whether it reads as the right person for a specific role. The rubric scores an aspiring data engineer and a working data analyst identically, though one is targeting the job the other already holds. There is no optimized profile in the abstract, only a profile well matched to a target. Optimizing in an unspecified direction produces a complete profile that generates no inbound. For the case where the profile does not exist yet rather than being mistargeted, the create a LinkedIn profile from scratch template covers the setup stage first.
A real job description for a role the user wants. The JD is written by the person doing the hiring, in the vocabulary they will use when they search. Three things to extract from it:
Then read three or four profiles of people currently in that role and observe how they describe work the candidate also does — for calibration, not for copying.
In descending order of leverage:
The manual version of this task is three to four hours: reading the JD closely, opening comparable profiles, and rewriting three fields. Profile writing services do the same work for $200–$800 with a turnaround measured in days. A chatbot can draft text but cannot open LinkedIn, so it only sees what is pasted into it, which removes both the live profile and the comparable profiles from the input.
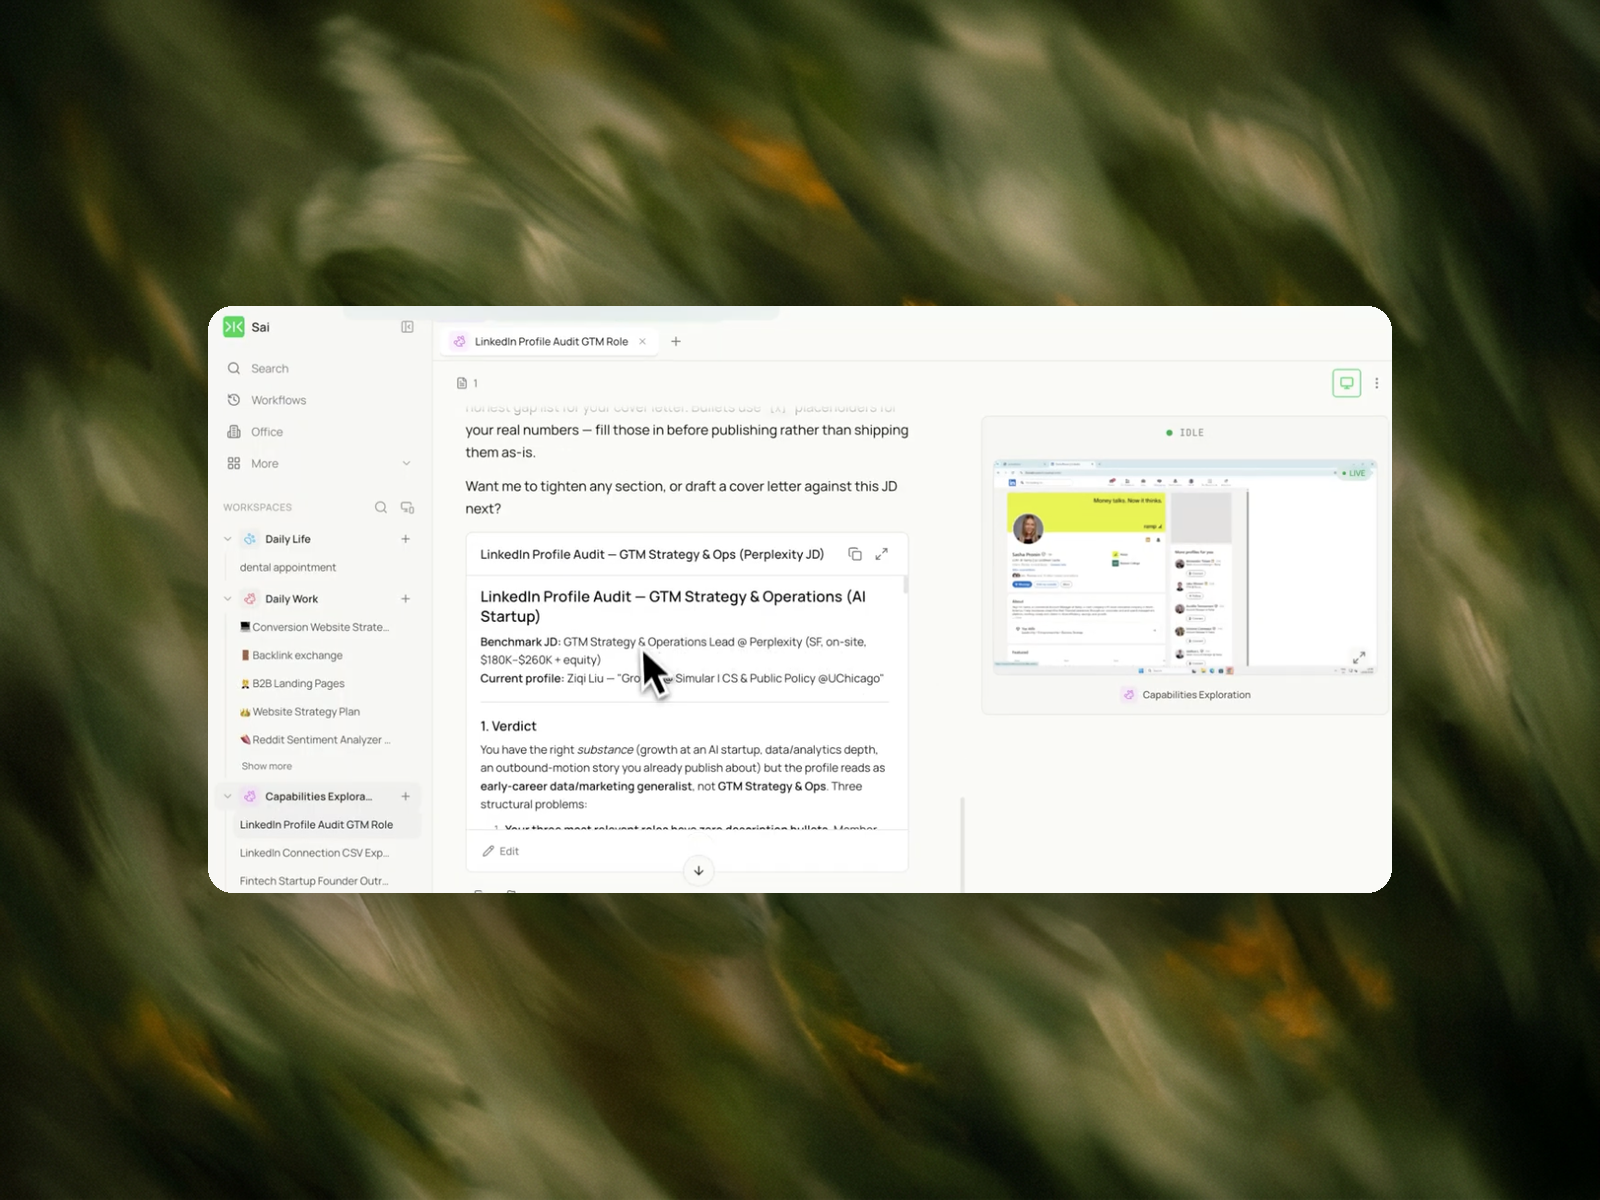
Sai runs the task as an autonomous computer: it operates a browser the way a person does rather than calling an API or replaying a fixed script. Given a job description link and a profile, it opens the profile and reads it as it actually renders, reads the JD, opens several profiles of people currently in that role, and produces a document that opens with a verdict on the gap between what the person has done and how the profile reads. In the example run, the profile belonged to someone with growth experience at an AI startup and real analytics depth, but it read as an early-career marketing generalist rather than the GTM strategy and operations lead the JD described. The document then names structural problems specifically — three of the most relevant roles carrying zero description bullets, a headline missing the target function — and drafts the replacements: a new headline, a rewritten About, and experience bullets built from real history in the JD's vocabulary. Where a bullet requires a number Sai has not seen, it leaves a bracketed placeholder rather than inventing one.
Profile rewriting fails in a specific way: an invented metric, a company the person never worked at, a responsibility lifted from a comparable profile rather than from the candidate's own history. A fabricated line in a professional profile is a liability, not a draft-quality issue. Reliability here means every claim traces to a source the run actually read — the profile, the JD, or a named comparable profile — and that gaps are marked as placeholders rather than filled. Reading the live rendered page rather than a cached export is part of the same property: a profile edited last week is read as it is now. The same read-the-live-page approach is used in the LinkedIn profile data extraction template, which collects structured fields across many profiles instead of rewriting one.
The comparison is against the two existing ways of getting this done. A profile writing service costs $200–$800 per profile and returns work in days, and re-targeting to a second role is a second engagement. Doing it manually costs three to four hours per target role, repeated each time the target changes. Running it as a task costs one run of about eight minutes plus review time, and re-running against a different JD costs another run rather than another engagement. The AI cost reduction is structural rather than a discount: the marginal cost per target drops close to zero, which is what makes benchmarking against three postings instead of one a reasonable thing to do.
Two ways this task repeats.
Running one profile against several job descriptions in the same session is batch processing of the useful kind: the vocabulary that appears across all three postings is the signal, and terms appearing in only one are that company's internal jargon. The overlap is what belongs in the headline.
Re-optimization is triggered by a change of target, not by the calendar. A profile tuned for one role is by definition less tuned for a different one, so chasing a different title, changing industries, or moving from individual contributor to management each warrant a fresh run against a fresh JD. For an active search, setting this up as a recurring task against saved postings keeps the profile aligned with what is currently being posted for that role. Profiles also drift for reasons unrelated to targeting — adding a promotion and adding a resume to a profile are separate maintenance tasks.